The price of autonomy
AI Agents Take an Early Lead. Humans Can Win the Longer Race
The first improvements come fast. Then the experiments keep running, the bills keep arriving, and progress stalls. METR’s expenditure horizon puts a price on the point where an autonomous agent should hand the work to a specialist.
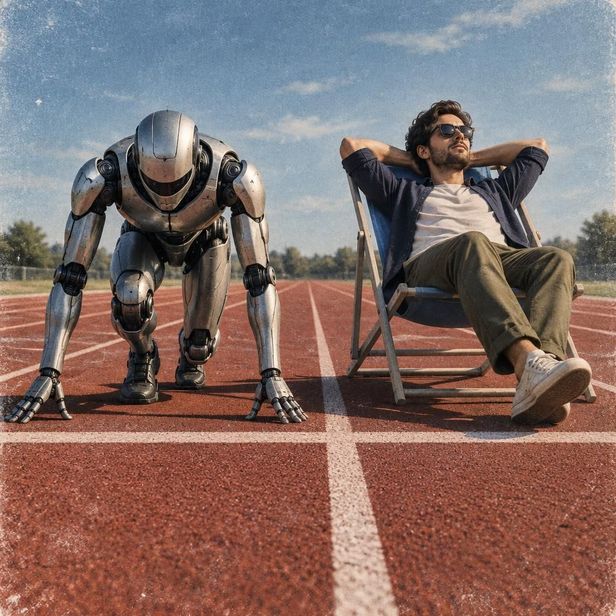
An AI agent can make a very good impression in its first few minutes. While a human is reading the code, checking the documentation and forming an initial hypothesis, the machine is already proposing changes, running tests and delivering results. From there, a tempting staffing policy practically writes itself: if it starts this well, let it keep working alone. Long projects have an awkward habit of spoiling that pitch. The next hour may be far less productive than the first. The machine keeps busy; useful progress slows to a crawl.
In a study published on July 21, METR proposes a way to measure that limit: the “expenditure horizon.” Researchers compare the improvements a human and an agent can deliver on the same budget. An agent may initially offer better value, picking up readily available optimizations and saving expensive human effort. As its returns diminish, the human performance curve can pull ahead. Their intersection marks the budget beyond which autonomous work loses its economic advantage over human work.
This adds an important dimension to the familiar discussion of task horizons. A claim that a model can handle several hours’ worth of human work usually refers to an assignment with a defined endpoint: fix a bug, implement a feature, pass a test. Research has a different kind of finish line. A system can be improved by one percent, then another, then substantially redesigned. What matters is how long someone—or something—can keep finding improvements, and what each improvement costs. A checkbox marked “task complete” ends the discussion far too soon.
METR tested the metric on the NanoGPT speedrun, an open competition to accelerate the training of a small language model on eight H100 GPUs. The required quality is fixed; participants change the implementation to reach it faster. Successful optimization produces a measurable reduction in training time, making it possible to track successive gains and ask whether additional spending buys additional progress. For an industry promising to automate AI research itself, this is also a test on home turf.
The agents started with code that had already been heavily optimized. Their baseline was a training run of roughly 85 seconds, achieved in March 2026. That matters. Building a working first version and improving a system that a community has already refined are very different challenges. In the latter case, many obvious opportunities have been taken. Finding the next gain demands a more precise understanding of where inefficiencies remain.
Agent runs were allowed up to five days and budgets of up to $10,000, including model API calls and GPU compute. Some models produced no verified improvement after their results were rechecked. Stronger models did make progress, but higher spending did not yield proportionate gains. Estimated expenditure horizons ranged from zero to roughly $3,300. Being able to keep an experiment running did not make it worth continuing.
For the human side of the comparison, the authors drew on NanoGPT’s contribution history and interviews with two active contributors. They estimated roughly 16 hours of labor for each one-percent improvement. At an assumed rate of $150 an hour, that comes to $2,400, rounded to a baseline of about $2,500. This supplied the human reference curve: how much improvement a given budget might buy if spent on a specialist.
The setup matters when interpreting the result. METR estimated human returns from the real world project; it did not recruit a cohort of people and race them against agents for two weeks. The approximately linear human trajectory comes from the calculation. Both the assumed wage and the estimated hours affect where the curves cross. A cheaper specialist would erode the machine’s advantage sooner; a more expensive one would extend it. The metric brings those assumptions into view, where they can be debated alongside model performance.
If we can estimate performance as a function of cost for both humans and agents, we can measure the “expenditure horizon” as the point at which those curves cross: the budget at which humans become more cost-effective than AIs.
The most interesting finding is that an autonomous agent can have a short economically useful run even when it has plenty of time left to work. Getting quick initial gains and sustaining further improvement are separate abilities. After a strong start, the agent must find less obvious solutions, test them and work through long sequences of failures. Every cycle consumes part of the budget.
It is tempting to attribute the difference to human intuition, learning and generalization. There is substance to that explanation. A specialist develops a working understanding of the system, connects findings across experiments and rules out entire families of unpromising approaches. Failed attempts can change that understanding and make subsequent attempts more valuable. An agent’s ability to accumulate research experience has to be built into the system. A long context window and permission to run another test do not, by themselves, make the next decision any better.
The NanoGPT experiment measures results and costs; explaining the plateau is a further research question. Planning, retention of earlier findings, experiment selection and verification could all play a part. The practical problem is already visible: autonomy can scale up the number of actions more readily than it scales the supply of useful new ideas. Brute force gets especially expensive when every hypothesis requires an actual compute experiment.
That makes a strong case for testing human–AI teams. An agent could handle the fast opening phase: inspecting code, preparing alternatives, making routine changes and running initial checks. A human could then use that groundwork to choose the next direction, revisit assumptions and tackle decisions that require a deeper understanding. The division would exploit the steep early rise in agent performance while giving the project a way forward once that rise flattens. Whether the combination actually outperforms either participant alone requires a separate comparison. METR’s findings give a concrete reason to run it.
In “They cut the staff. Did AI cost more?”, we examined the accounting behind autonomy: payroll disappears from one line, while compute, integration, verification and error correction appear elsewhere. NanoGPT adds another expense: continuing to work after the productive approaches have run out. An autonomous agent can, in theory, work around the clock. Its bills can arrive around the clock, too. The expenditure horizon gives that observation a measurable question: when did the next dollar stop earning its keep?
For companies, this changes the deployment decision. Buying an abstract “digital employee” gives way to identifying where an agent is useful and when to hand the work to a person. That point will vary with the model, task, labor rate and compute cost. Finding it means tracking the full path to a usable result, including verification and failed attempts. The first ten minutes make an excellent demo. They are a poor basis for a layoff decision.
METR directs attention to what happens after the impressive opening, when sustained progress becomes expensive. The stronger agents in its experiment found improvements, but their economic advantage was limited. That leaves a substantial role for people: carrying research forward when the machine’s available moves no longer pay off. A capable autonomous worker should turn more budget into more useful output. When the main thing growing is the bill, handing the task to a human belongs inside an efficient system.
Imagerly.Ai · No. 07 · September 2026