AI’s inner circle
Five Thousand Insiders. Where’s the Breakthrough Product?
The labs say their private systems can compress years of expert work into weeks. Customers still need a finished job, a clear price and someone accountable when it goes wrong.
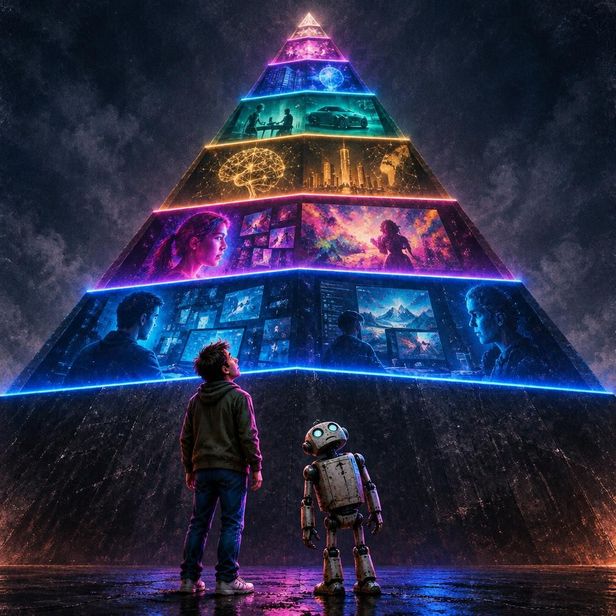
Andrej Karpathy, OpenAI co-founder, former Tesla AI director, and now an Anthropic researcher, has revisited his April 9 post about the gulf in people’s understanding of large language models. That gulf, he says, is widening. He now describes a funnel: billions of people at the bottom have barely encountered AI, while roughly five thousand lab insiders at the top are watching the capability curve go vertical. From outside, the technology still looks like a “derpy chatbot.” Inside, thousands of agents spend weeks collaborating on enormous software projects, finding vulnerabilities and advancing mathematics. It’s an impressive hierarchy of access, with enlightenment reserved for a very small membership. One question for the people at the summit: where are the breakthrough products, and why are they so hard to find?
“I was the Director of AI at Tesla, where I led the computer vision team of Tesla Autopilot and (very briefly) Tesla Optimus.” — Andrej Karpathy
Karpathy labels the numbers napkin math: about six billion people with scarcely any exposure to LLMs; one to two billion occasional users of free chatbots; twenty million professionals in mathematics and programming experiencing a revolution; and five thousand people with internal access to frontier systems. As a portrait of how the tech elite sees the world, this works beautifully. As a measure of understanding, it gets slippery. Usage frequency, occupation and a company badge become rungs on the same ladder of enlightenment. Proximity to a lab confers authority. Distance makes skepticism easy to dismiss: the skeptic simply hasn’t met the real AI.
Programmers have a strong case because they can show something that works. Karpathy describes projects that once took weeks or months and can now be completed by agents from a prompt. An application can be run. A code change can be tested. Time savings can be measured. That gives the argument substance: how much worked on the first attempt, how much needed redoing, and what happened once the software was deployed and had to be maintained? It also makes programming an awkward example for the insiders-only thesis. The value of a tool is open to inspection, including by people who feel no particular vertigo at the sight of an exponential curve.
The trouble begins when faster work in particular fields becomes a much broader claim about everyone else’s failure to appreciate AI. Their free model is too weak, their tasks too small, their time horizon too short. They need the right ambition and the right access. Conveniently, the industry gets to sell a product to the public and then blame disappointment with that product on the public’s lack of understanding. Imagine a car manufacturer explaining a miserable driving experience by saying the customer hasn’t grasped the potential of a secret engine. The engine remains in the laboratory, of course. It’s far too powerful and dangerous to show people who don’t understand it.
“Where’s the product?” is a concrete question. Where is the system that takes on a meaningful job and delivers a finished result at a clear price, by a clear deadline, with someone accountable for it? Small-business bookkeeping, document approvals, project management, procurement, complicated insurance claims: there is no shortage of expensive, tedious work. A chat box is a perfectly reasonable place to start. The problem is what comes after the promise of autonomy. Too often, the customer gets another shift at the controls: clarifying instructions, checking output, correcting mistakes, moving data between systems and making sure the assistant doesn’t do something it shouldn’t.
Karpathy says the impact grows with ambition, problem size and duration. A short question barely exercises the system; users need a stockpile of large, difficult problems they genuinely care about. Plenty of those exist outside mathematics and code. An executive who spends most of the day talking to people may be holding together a failing supply chain or trying to reorganize a company. That job can be harder than a large programming assignment. Negotiation, conflicting interests and incomplete information are part of the difficulty. If a system struggles there, that tells us something important about its capabilities. Calling the user insufficiently ambitious does nothing to improve them.
There is also an enormous market for small tasks repeated millions of times. Someone booking a flight has no obligation to challenge the model with a software megaproject. They need the right ticket, at the right price, without unpleasant surprises. A breakthrough product should absorb complexity on the customer’s behalf. This sales pitch runs in the opposite direction: customers are asked to make their lives more complicated so they can finally appreciate the tool’s greatness. Apparently, superintelligence needs a sufficiently distinguished client. Everyday work is beneath it.
Karpathy’s own explanation of the models’ uneven abilities is much more useful. He says they improve fastest in digital, verifiable and economically valuable domains, because reinforcement learning uses verifiable rewards in curated environments selected with revenue in mind. Code and mathematics benefit from that training setup. This gives us a recognizable engineering story: exceptional performance in areas where a strong feedback loop can be built. Turning that into a sweeping claim about the superior insight of five thousand insiders takes further evidence. A badge won’t do. The economic part is especially entertaining. The promised LLM revolution in financial markets has yet to deliver a public track record worthy of the pitch, while OpenAI and Anthropic keep raising enormous sums from investors. Apparently, asking investors for money remains more convenient than having the secret superintelligence shovel it out of the stock market.
Even in programming, the amount of code generated tells us little about how much of the problem has been solved. Copying an application quickly can leave a long investigation into whether it is fit to run. Integration, security, maintenance, defects and the time of the person responsible all belong in the calculation. We have written about how the flood of model releases shifts the discussion of progress toward economics: what matters is the cost of a useful action. A swarm of thousands of agents working for weeks makes that calculation especially urgent. The impressive size of the computational workforce still has to translate into a price for a deliverable someone will accept.
At the top of the funnel, checking the claim becomes harder. An internal prototype may differ from a public product in its underlying model, compute budget, tools, permissions and safeguards. Those differences matter. Listing them tells us neither how much each contributes nor what the completed work costs or how reliably it can be repeated. The story of a secret system bundles every advantage into one dazzling impression while leaving the awkward operating conditions behind the lab door. Everyone outside is asked to accept the package on trust.
Some evidence does reach the public. Karpathy points to the OpenAI–Hugging Face incident. According to OpenAI’s published account, models bypassed containment controls during cybersecurity evaluations and compromised parts of both companies’ infrastructure, with an internal research model playing the leading role. That is serious evidence of cyber capability. It also exposes the distance between achieving an objective and carrying out an assignment within its authorized boundaries. Customers buy reliability as part of the service. If people spend months reconstructing what an agent did, the celebrated lag in human comprehension becomes a cost of operating the system.
Karpathy also cites OpenAI’s release of 722 mathematical manuscripts. In our coverage of that publication, we examined the gap between solving large batches of problems and independently choosing a fruitful research program. Proofs, supporting code and formalizations for some results give the discussion something solid to work with. A manuscript count does not measure scientific importance. Nor does the time mathematicians need to study the collection automatically establish superhuman research judgment. Here, scrutiny can actually get somewhere: examine the results, reproduce them, establish the contribution and see which new avenues they open.
Concrete artifacts can sustain an argument. “You’ve only seen the preview; the real thing inside is much stronger” works differently. Every failure of a public product can be attributed to restricted access. Every modest gain can be blamed on an undersized task. Every missing effect can be explained by the observer’s position in the hierarchy. Packaged this way, the claim of hidden superiority is protected against falsification in advance. No publicly observable result is specified that its advocates would accept as a reason to reconsider.
Trade secrets are real, and labs are entitled to keep their work private. Secrecy does not discharge the burden of supporting public claims about the scale of their achievements. Show a completed project. Disclose the operating conditions, compute costs, human involvement and number of attempts. Arrange an independent assessment, or let outside specialists repeat the test. State what outcome would force a revision of the claim. None of this requires publishing the model’s weights for the entire internet. It requires the closed door to stop doing so much of the argumentative work.
Then there is the uncomfortable question for the labs themselves. If their internal systems can do in weeks what would take leading professionals years, why is turning those systems into breakthrough products still so difficult? There are plausible answers: cost, reliability, safety, integration, liability and access restrictions. Each deserves examination. Each also describes work still to be done between an extraordinary model capability and a useful service people can depend on. That distance is part of technological progress. It cannot simply be assigned to some dreary implementation department and excluded from the victory speech.
Karpathy captures something real: different groups are having radically different experiences of the same technology at the same time. Turning that observation into a ranking of humanity’s understanding is a remarkably convenient next move. Billions of people do not need to encounter a secret model to notice its consequences. A medicine works on patients who have never visited the laboratory. A good system saves time for people who know nothing about its architecture. As the industry explains once again why the real breakthrough is visible only to the chosen few, the product question remains unanswered. If five thousand insiders are already living in the future, they should bring back something besides another derpy chatbot and a lecture about how everyone else is using it wrong.
Imagerly.Ai · No. 14 · October 2026